This content has been automatically translated from Ukrainian.
A person perceives the world in several ways at once. We can look at a photograph, read the caption below it, listen to explanations, and pay attention to the intonation of the interlocutor. All these sources of information complement each other and help to better understand the situation.
For a long time, computer systems operated differently: one program analyzed text, another recognized images, and a third processed sound. Multimodal systems have learned to combine several types of data within a single task.
What does the word "multimodality" mean
Multimodality is the use of several ways to transmit or perceive information. The first part of the word, multi-, means "many," while modality in this context refers to a specific format or channel of information.
The main modalities include:
- text;
- images;
- speech and other sounds;
- video;
- gestures and movements;
- spatial and sensory data.
Multimodality existed long before the advent of modern artificial intelligence. For example, a film combines video, music, speech, and text subtitles, while a textbook includes written text, photographs, maps, tables, and diagrams. A presentation can also be called multimodal if the report is accompanied by slides, graphs, or video recordings.
What is multimodal AI
Multimodal artificial intelligence is a system capable of processing and combining information of several types. For example, such a model can receive a photograph and a text question, analyze them together, and then formulate an answer.
A regular text model works with written queries and produces text results. A computer vision system can determine what is depicted in a photograph but may not necessarily be able to engage in a conversation about what it sees. A multimodal model combines different ways of working with data.
It can be shown a picture of a faulty device and asked what the indicator on the panel means. The system will analyze the image, try to read the visible inscriptions, and explain the problem in words. Similarly, it can process a graph, describe a scene in a video, or respond to a voice question.
It is the ability to receive, combine, and analyze text, images, audio, video, and other types of data that underlies multimodal AI.
How multimodality works in AI
For a computer to correlate different modalities, the data must be transformed into numerical representations. The method of such transformation depends on the architecture of the specific model. Text, for example, can be broken down into tokens, while images can be divided into individual sections or visual features. An audio recording is also divided into elements that the system can recognize speech and other sound characteristics.
Next, the model establishes connections between these representations. During training, it can learn that certain shapes and colors in an image correspond to the word "whale," while a specific audio fragment means the same word in spoken language.
One of the main tasks of such a system is to correctly associate related elements. For example, in a video, it needs to match words with sounds and corresponding events in the frame, while analyzing a document requires linking text with tables, diagrams, and illustrations.
A multimodal model does not necessarily perform equally well with all formats. One system may confidently analyze texts and photographs but not support video. Another may recognize speech and respond vocally but not create images.
Therefore, multimodality does not mean that the system can do absolutely everything. It only indicates the ability to work with at least a few types of data.
Input and output modalities
When describing multimodal AI, it is important to distinguish between the information that the model receives and the result that it can produce.
Input modalities are formats that the system can accept and analyze. For example, a user can upload a photograph and ask a text or voice question about it.
Output modalities are formats in which the model produces results. It can respond in text, generate images, vocalize messages, or create videos.
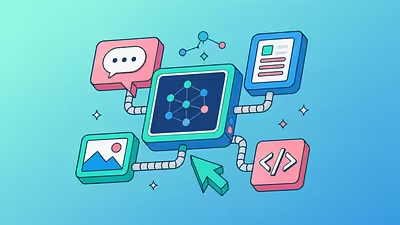
The system can be multimodal only at the input. For example, it analyzes text and images but responds exclusively in text. Another model can be multimodal both at the input and output: perceiving text, sound, and photographs, and in response generating text, voice, or images. This principle—transforming data of one type into a result of another type—is used by modern multimodal models.
How multimodal AI differs from generative AI
The concepts of multimodal and generative describe different properties of a system.
Generative AI creates new content: text, images, music, video, or code. Multimodal AI works with several types of data. One model can have both properties, but these terms are not synonymous.
For example, a system that receives a text description and creates an image based on it connects two modalities—the textual and the visual. A more complex model can receive a photograph of a room, analyze it, consider the user's preferences, and generate a new interior design option.
At the same time, a multimodal system does not necessarily have to create new content. It can simply analyze video along with sound to determine what is happening in the frame.
Where multimodal systems are used
One of the most obvious examples is chatbots, which can not only receive written questions but also accept photographs, documents, audio recordings, or videos. However, the application of multimodal AI is much broader.
In medicine, such systems can help correlate imaging studies with text records from doctors and other patient data. In education, they can explain diagrams, analyze completed tasks, or describe learning materials. In robotics, combining data from cameras, microphones, and sensors helps machines navigate in space.
Multimodal technologies are also used for creating subtitles,
The article was successful in structure and generally correct in facts. I clarified the origin of the term, simplified the technical explanation, removed a few repetitions, and more accurately distinguished between multimodal and generative AI. Here is the final version.
What is multimodality and why is it needed for artificial intelligence
A person perceives the world in several ways at once. We can look at a photograph, read the caption below it, listen to explanations, and pay attention to the intonation of the interlocutor. All these sources of information complement each other and help to better understand the situation.
For a long time, computer systems operated differently: one program analyzed text, another recognized images, and a third processed sound. Multimodal systems have learned to combine several types of data within a single task.
What does the word "multimodality" mean
Multimodality is the use of several ways to transmit, perceive, or process information. The first part of the word, "multi-," indicates multiplicity, while modality in this context refers to a specific type or channel of information.
The main modalities include:
- text;
- images;
- speech and other sounds;
- video;
- gestures and movements;
- spatial and sensory data.
Multimodality existed long before the advent of modern artificial intelligence. For example, a film combines a video sequence, music, speech, and text subtitles, while a textbook includes written text, photographs, maps, tables, and diagrams. A presentation is also a multimodal format if the report is accompanied by slides, graphs, or video recordings.
What is multimodal AI
Multimodal artificial intelligence is a system capable of processing and combining information of different types. Such data can include texts, images, sound, video, and signals from sensors. This is how multimodal AI defines IBM in its technology review.
For example, a model can receive a photograph and a text question, analyze them together, and then formulate an answer. It can be shown a picture of a faulty device and asked what the indicator on the panel means. The system will try to recognize elements of the image, read visible inscriptions, and explain what it sees in words.
A unimodal system works only with one type of data. For example, a text model receives and generates text, while an image recognition program analyzes photographs. A multimodal model can combine these capabilities.
How multimodality works in AI
A computer does not perceive a photograph, phrase, or sound in the same way a person does. First, different types of information need to be transformed into numerical representations that the model can process.
Text is usually broken down into tokens—words, parts of words, punctuation marks, and other elements. An image can be divided into small sections from which the system extracts visual features. An audio recording is also converted into numerical data that allow for analyzing speech, tone, pitch, and other characteristics.
The next task is to establish correspondence between different modalities. For example, the system must link the word "whale" with images of whales, and a specific fragment of an audio recording with the pronunciation of that word. In more complex cases, it needs to match individual moments of a video with sounds, dialogues, or text subtitles.
Specialized components may be used for this, which initially process each type of data and then combine the obtained information. Another approach involves working with different modalities within a more holistic model. The main task in both cases is not just to accept several formats but to correctly establish connections between them.
Input and output modalities
When describing multimodal AI, it is important to distinguish between the information that the model receives and the result that it can produce.
Input modalities are formats that the system can accept and analyze. For example, a user can upload a photograph and ask a text or voice question about it.
Output modalities are formats in which the model produces results. It can respond in text, generate images, vocalize messages, or create videos.
The system can be multimodal only at the input. For example, it analyzes text and images but responds exclusively in text. Another model can work with several formats both at the input and output. Google Cloud also notes that multimodal models can accept data of one type and transform it into a result of another type.
At the same time, multimodality does not mean that the system can work with all possible formats. One model may analyze texts and photographs but not support video. Another may recognize speech and respond vocally but not create images.
How multimodal AI differs from generative AI
The concepts of "multimodal" and "generative" describe different properties of a system.
Generative AI creates new content: text, images, music, video, or code. Multimodal AI works with several types of information. One model can have both properties, but these terms are not synonyms.
For example, an image generator that takes a text description and creates an image based on it works with two modalities: textual and visual. A more complex system can receive a photograph of a room, consider the written preferences of the user, and generate a new interior design option.
At the same time, a multimodal system does not necessarily have to create new content. It can simply analyze video along with sound to determine what is happening in the frame.
Where multimodal systems are used
One of the most obvious examples is chatbots, which can not only receive written questions but also accept photographs, documents, audio recordings, or videos. However, the application of multimodal AI is much broader.
In medicine, such systems can correlate imaging studies with text records and other patient data. In education, they can explain diagrams, analyze handwritten tasks, or describe learning materials. In robotics, combining information from cameras, microphones, and sensors helps machines navigate in space.
Multimodal technologies are also used for creating subtitles, voice control, speech translation, image search, and assisting people with visual or hearing impairments. For example, a system can audibly describe objects in front of the camera or convert spoken language into text.
Why multimodal models make mistakes
The presence of multiple sources of information does not make a system infallible. A model may misrecognize small text, confuse similar objects, overlook context, or inaccurately interpret intonation.
The quality of the material also matters. A blurry image, noisy audio recording, cropped document, or poorly formulated question increases the likelihood of error. Additionally, the system may confidently describe a detail that does not actually exist—resulting in a kind of AI hallucination.
Challenges also arise when different sources contradict each other. For example, a caption under a photograph may not match the image, and an audio track may not align with the video sequence. The model must determine which information to trust, but it does not always do this correctly.
Therefore, the results of multimodal AI should be verified, especially when it comes to medicine, safety, finance, or other fields where errors can have serious consequences.
Multimodality brings interaction with a computer closer to familiar human communication. Instead of translating everything into text commands, a user can show an object, ask a question verbally, or send a document. The system, in turn, combines these signals and responds in an appropriate format. It is the ability to work not with one isolated channel but with several types of information that constitutes the essence of multimodality.